Introduction
Hello again,
It’s been a while. Lately most of my time went into Kubernetes and OpenShift reviews, and one question kept coming back. It isn’t “what can this ServiceAccount do?”. It’s “what can this ServiceAccount end up becoming?”. Those are two different questions, and the second one is the one that hurts in a real incident.
So I built a tool for it. Today I’m releasing nhi-reach v0.1.0 (2026-10-08, Apache-2.0).
⚠ Advertisement: The techniques & software explained here are purely educational and defensive. The tool is read-only, but you should still only point it at clusters you’re allowed to audit.
The problem
When you review RBAC you normally go identity by identity. You open a Role, read the verbs, see nothing like * on *, and move on. That works until two harmless-looking permissions join up.
Here are three of the jumps I care about:
- NR-001, workload creation. If an identity can create workloads in a namespace, it can run a Pod as any ServiceAccount in that namespace, because Pods can run as any SA there. Careful, this one is conditional: the workload still has to be admitted and actually run, and that’s a step outside the model.
- NR-002, impersonation. If you can
impersonateanother identity, you get its permissions. Simple as that. - NR-003, token request. With
createonserviceaccounts/tokenyou can ask the API for a token of that SA and use it.
Now picture SA A that can create Deployments in a namespace where SA B lives, and B can impersonate C, and C is bound to cluster-admin. None of the three Roles looks scary when you read it alone. But the chain ends at cluster-admin.
To be honest, I’ve done this by hand on a whiteboard more than once and it’s slow. Also you miss things. That’s the point of the tool.
How it works
nhi-reach is a CLI written in Go. It’s defensive and read-only. It looks at non-human identities (ServiceAccounts) and works out escalation paths towards critical targets.
First it resolves the effective permissions of each ServiceAccount. That means it counts implicit groups, handles resourceNames and materializes aggregated ClusterRoles, because otherwise you’re reasoning about a cluster that doesn’t exist.
After that it lists paths to two targets:
- equivalence with cluster-admin
- reading Secrets in sensitive namespaces
There’s also a third target, node control. It isn’t evaluated. The tool accepts it and reports it as a gap, so you don’t read silence as “clean”.
The edges come from a small catalog: six documented hops (NR-001 to NR-006) plus the direct binding-to-cluster-admin edge. Every hop cites the official Kubernetes/OpenShift page that justifies it, and if there’s no official source it doesn’t go in. You can see them with:
nhi-reach rules
It has three output formats:
- a table, for the terminal
- versioned JSON (
schema_version1), for pipelines - a self-contained HTML report: one file, no network requests, with the graph embedded. You can mail it to someone and it’ll open.
For each path it also proposes cuts, the grants you’d remove to break it. Each cut is verified in the model and up to --max-depth. I want to be very clear on this: it is not a guarantee about your real cluster. The model is a model.
A few more things I spent too much time on, on purpose:
Live mode. snapshot -o DIR captures the cluster and analyze --live analyzes it directly. Read-only is enforced in the HTTP transport itself, which only lets get/list through. It isn’t a line in the README asking you nicely.
Determinism. The same snapshot gives exactly the same output, byte for byte, in all three formats. The repo compares golden files byte by byte, so if something changes order the tests complain.
Secrets are never stored. Only metadata, type and the key names (dataKeys). Never data or stringData. Not in snapshots, not in logs, not in reports.
Real test
I tested it in a kind lab on an arm64 VPS with rootless podman. snapshot wrote 259 objects. Then I ran the offline analysis (analyze --from) and the live analysis against the same state, and they came out byte-identical (clean cmp). The bounded table exercises all eight edge types.
The lab cost 658.9 MB of RAM and 46 MB of disk, so you don’t need a big machine.
A small fun fact: the default cluster that kind installs ships 45 ServiceAccounts in kube-system. System identities aren’t sources by default (0 system sources), but they’re still used as intermediate hops. With --include-system you get 3.
I also ran benchmarks on a large synthetic fixture (not a cluster). The cut verification step dominates the cost, around 63–69× compared with the analysis without the rebuild. So the recommendation was to make verification opt-in behind a --verify-cuts flag. Actually that’s not implemented yet. In v0.1.0 verification is still on by default. What is promised is debt, so I’m not promising a date.
How it compares
There are other tools here and I’d rather say where this one fits than pretend it’s alone.
nhi-watch does inventory and scoring of identities, and it does it well. But it looks at each identity in isolation and doesn’t chain permissions. I see nhi-reach as complementary to it, not a replacement.
KubeHound (Datadog) is the big one for attack-path graphs in Kubernetes. Compared with it, nhi-reach is a single offline binary, focused on non-human identities, with cuts verified in the model. Also, the KubeHound homepage and attacks index I checked on 2026-10-07 don’t mention OpenShift SCCs. That isn’t a criticism. It’s just a different scope.
What it does not do
This is the part I’d read first if I were you:
- Node control is not evaluated. It’s reported as a gap.
- NR-007 (OpenShift SCC) is planned, but it isn’t implemented.
--verify-cutsis not in this release.- Cuts are verified in the model and up to
--max-depth. Nothing more. - I’ve only tested it in a kind lab with a single Kubernetes version. Not against a production cluster. If you run it on one, I’d really like to know how it went.
And it doesn’t claim to find every path. It finds the ones its catalog describes, inside the depth you give it.
Try it
You don’t need a cluster to try it. The repo ships synthetic fixtures:
go run ./cmd/nhi-reach analyze --from testdata/light/hit
For installing it there are prebuilt binaries for linux, darwin and windows (amd64 and arm64) with checksums, or go install (needs Go 1.25+). There’s a container too, but the binaries are the easy way for now.
And if you want to see it before running anything, this is the table report against a disposable lab cluster with RBAC misconfigured on purpose. Every route in it is synthetic:
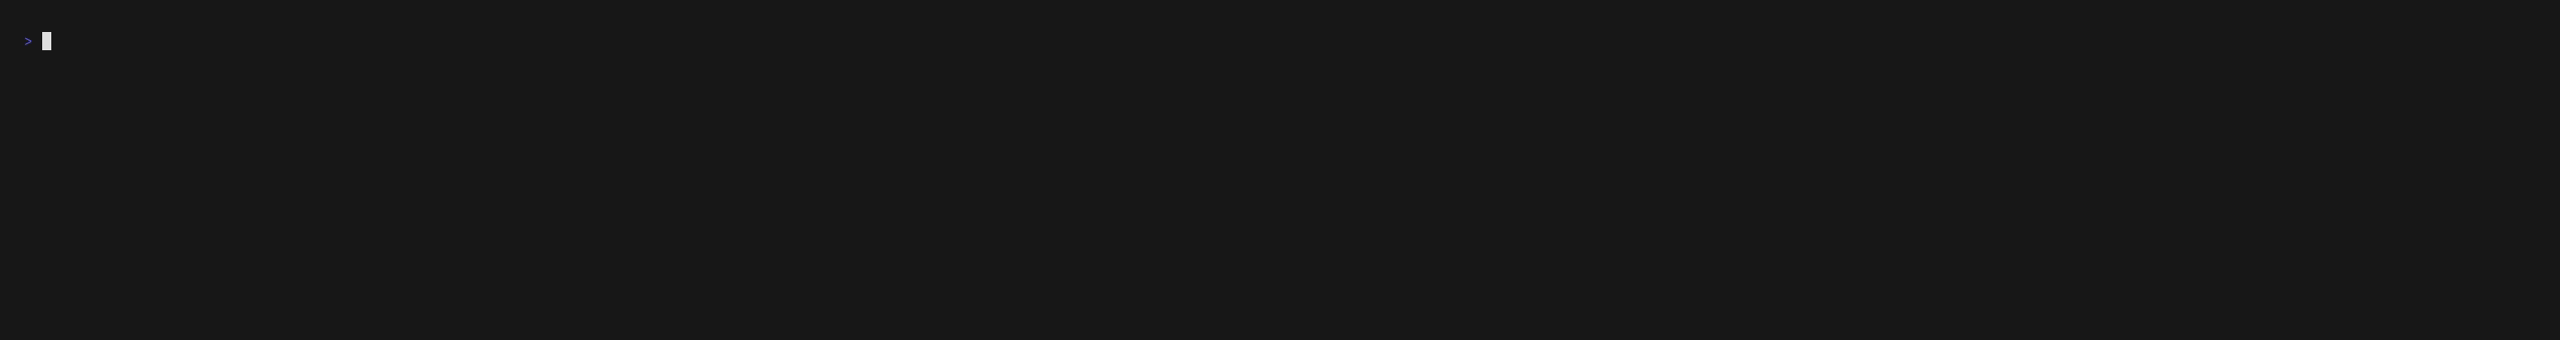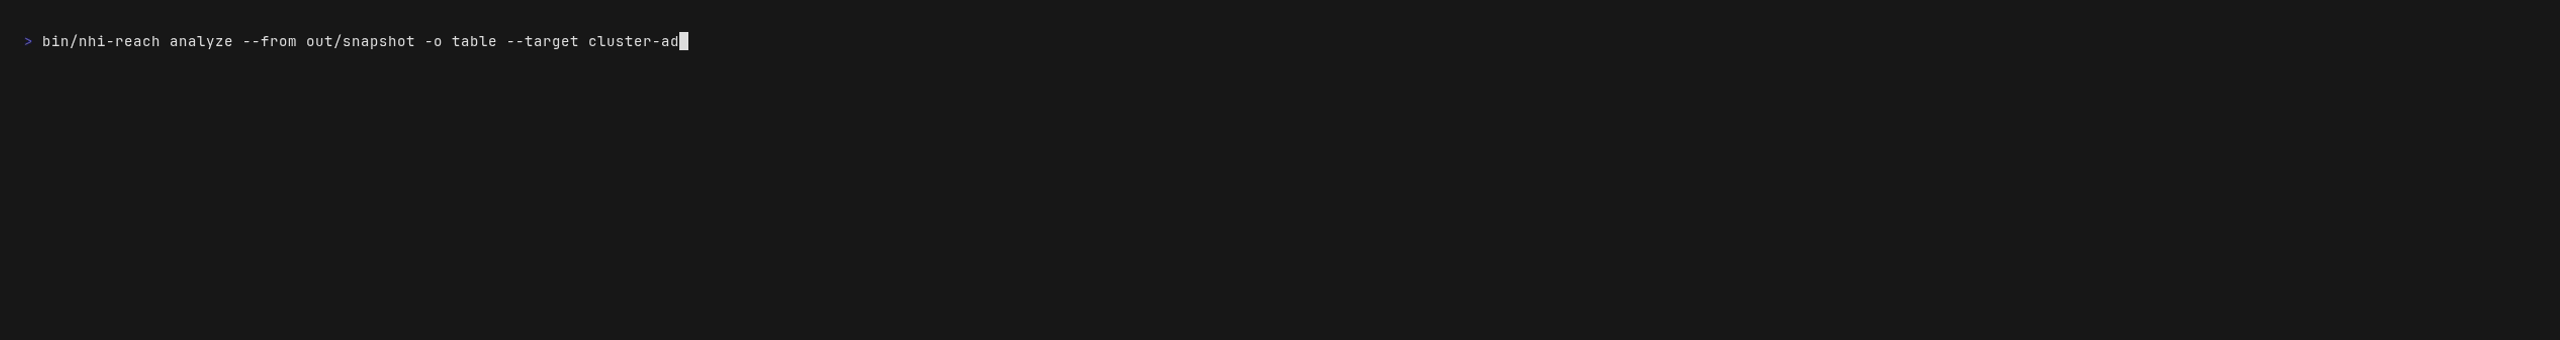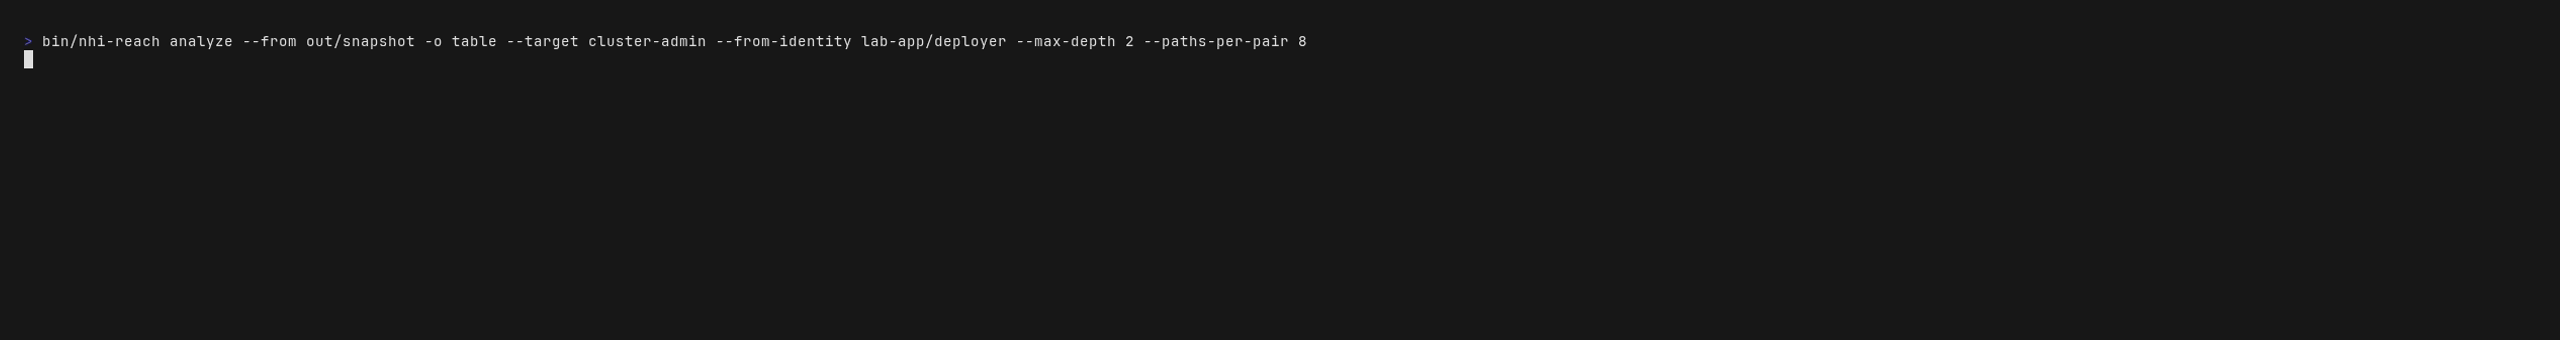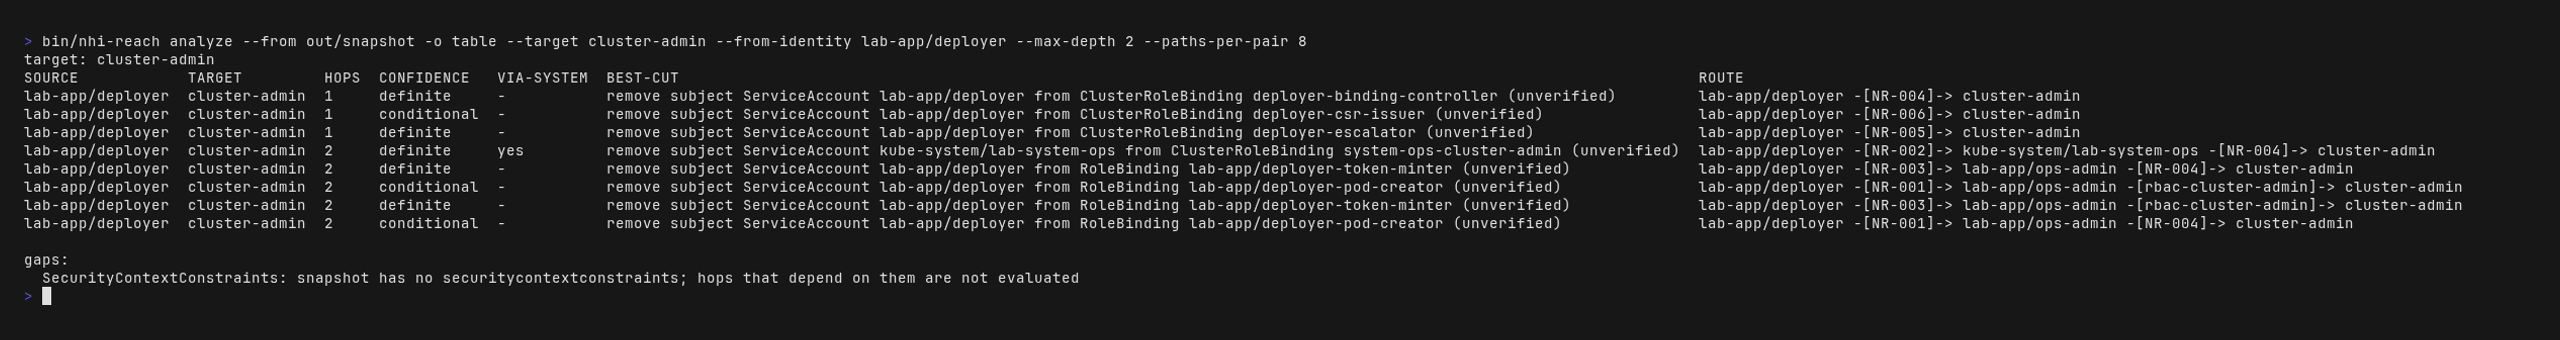
The same demo is in the README, with the recording script that reproduces it.
Achieved
- Effective permissions per ServiceAccount (implicit groups,
resourceNames, aggregated ClusterRoles) - Paths to cluster-admin and to Secret reads in sensitive namespaces
- 6 documented hops + the direct binding edge, each one with its official reference
- Table, JSON and self-contained HTML, byte-for-byte deterministic
- Live mode with read-only enforced in the transport
- Secrets never persisted
- Offline and live identical on a real kind lab (259 objects)
Conclusion
This started as “I’m tired of drawing arrows on a whiteboard” and ended up as a v0.1.0 I’m honestly happy with. It’s small and it says what it doesn’t know.
If you run it, tell me which chains you find. And mostly tell me the ones it misses, because that’s how the catalog grows. Open an issue on the repo or ping me.
Bibliography
https://github.com/d4rpell/NHI-reach
https://kubernetes.io/docs/concepts/security/rbac-good-practices/
https://kubernetes.io/docs/concepts/security/rbac-good-practices/#workload-creation
https://github.com/Zyrakk/nhi-watch
https://github.com/DataDog/KubeHound
https://kubehound.io/
https://kubehound.io/reference/attacks/
Thanks for reading ;)